Builder और AI एजेंट API प्लेबुक
LLM उत्तरों को ग्राउंड करने, एजेंट वर्कफ़्लो बनाने और प्रोडक्शन AI फ़ीचर्स शिप करने के लिए ट्यूटोरियल, तुलनाएं और उपयोग के मामले।
Add Real-Time Web Search to an n8n AI Agent
n8n has no built-in web search node, and the two workarounds people reach for behave very differently once an AI Agent is driving them. Here is the HTTP Request Tool route, the sub-workflow route, and the failure mode that sends most people back to the forum.
A LangChain Web Search Tool in 20 Lines (Python)
LangChain's bundled search wrappers hide the two decisions that actually matter: what shape the results arrive in, and who pays for the calls the agent makes and then throws away. Writing the tool yourself takes twenty lines and puts both back in your hands.
Give a CrewAI Crew Real-Time Web Search
A crew is several agents with the same tools, which means a tool that is slightly too expensive or slightly too chatty gets that flaw multiplied by the number of agents. Here is the search tool written both ways, and the two settings that stop a crew from searching the same thing four times.
Web Search as a Tool in the Vercel AI SDK
The AI SDK gives you a typed tool in about fifteen lines — and then two things bite: the model answers with empty text because the loop stopped at the tool call, and the key ends up in a client bundle. Both have one-line fixes.
A Dependency Vulnerability Scanning API for AI Agents: OSV.dev, CVSS Scores, and Fix Versions in One Call
OSV.dev is the best free vulnerability database in open source, and its API gives you everything except the one field you need to make a decision: the number. Here's how to turn advisories into a threshold you can branch on.
WHOIS Is Dead, Use RDAP: A Domain, IP, and ASN Lookup API That Returns Real JSON
Every WHOIS parser is a pile of regexes against text that changes per registry. RDAP fixed that years ago and almost nobody noticed. Here's what changed, why registrant contacts are empty, and how to query all three object types with one parameter.
EU VAT Validation API: Using VIES Correctly, Including the Parts That Trip Everyone Up
VIES is the only authoritative source for EU VAT validation, and it has three behaviours that quietly corrupt naive integrations: it answers 200 for everything, two member states withhold identity, and national systems go offline. Here's how to handle all three.
Entity Resolution With LEI: A GLEIF Lookup API for Counterparty KYC and Ownership Trees
"Apple Inc.", "Apple, Inc." and "APPLE INC" are three strings and one company. The LEI is a 20-character code that says so unambiguously, in every jurisdiction, and the data is public domain.
2026 में मुफ़्त IP Geolocation APIs: सटीकता, rate limits, और कब भुगतान करें
IP geolocation एक सुलझी हुई समस्या लगती है, जब तक आप बारीक अक्षर नहीं पढ़ते: केवल गैर-व्यावसायिक license, केवल-HTTP मुफ़्त tiers, महीने में 100 requests की सीमा, या ऐसे 'मुफ़्त' plans जो सिर्फ़ देश लौटाते हैं। यह गाइड 2026 के असली मुफ़्त विकल्पों की तुलना करती है — self-hosted GeoLite2, ip-api.com, IPinfo, ipstack, ipgeolocation.io और API Pick — सटीकता के ईमानदार आँकड़ों और एक निर्णय गाइड के साथ।
निवेश रिसर्च एजेंट कैसे बनाएं: बाज़ार, फंडामेंटल, SEC और आर्थिक डेटा एक ही API में
एक निवेश-रिसर्च एजेंट को पाँच अलग डेटा परतें चाहिए — कीमतें, फंडामेंटल, filings, मैक्रो और समाचार — हर एक आमतौर पर एक अलग वेंडर, key और schema। यहाँ बताया है कि कैसे इन पाँचों को एक ही endpoint सेट के पीछे जोड़ें, काम करने वाले कोड और लागत के गणित के साथ।
एक CVE और वल्नरेबिलिटी-इंटेलिजेंस एजेंट बनाएँ: CISA KEV, NVD, EPSS और MITRE ATT&CK एक ही API में
हर सुरक्षा टीम CVEs में डूबी रहती है। संकेत गंभीरता नहीं है — संकेत यह है कि क्या किसी वल्नरेबिलिटी का शोषण हो रहा है और इसकी कितनी संभावना है। यहाँ बताया गया है कि NVD, CISA KEV, EPSS और ATT&CK को मिलाकर एक ऐसा एजेंट कैसे बनाएँ जो जवाब दे कि 'मैं पहले किसे पैच करूँ?'
AI एजेंट्स के लिए रियल-टाइम मार्केट डेटा API: स्टॉक, क्रिप्टो, फॉरेक्स और ETF एक ही endpoint में
ज़्यादातर मार्केट-डेटा API डैशबोर्ड और क्वांट पाइपलाइनों के लिए बने थे, LLM एजेंट्स के लिए नहीं। जब आपका उपभोक्ता एक मॉडल हो तो क्या बदलता है — प्राकृतिक भाषा की queries, सभी asset classes में एक ही shape, only-on-success बिलिंग — और API Pick Markets मौजूदा खिलाड़ियों से कैसे तुलना करता है, यह यहाँ देखें।
कंपनी फंडामेंटल्स API: फाइनेंस एजेंट्स के लिए बैलेंस शीट, कैश फ्लो और इनसाइडर ट्रेड्स
कीमतें बताती हैं कि बाज़ार क्या सोचता है; फंडामेंटल्स बताते हैं कि वह सही है या नहीं। यहाँ AI एजेंट्स के लिए ढाली गई एक फंडामेंटल्स API है — स्टेटमेंट्स, डिविडेंड और इनसाइडर ट्रेड्स एक ही endpoint में — और यह कच्चे SEC EDGAR और स्टेटमेंट-API वेंडर्स के मुकाबले कैसी है।
AI एजेंट्स के लिए आर्थिक डेटा API: FRED, BLS, World Bank और IMF एक ही कॉल में
FRED का API बेहतरीन है — और अमेरिका-केंद्रित, सीरीज-ID पर आधारित, और कई मैक्रो स्रोतों में से एक जिसकी आपको अंततः आवश्यकता पड़ेगी। यहाँ एक आर्थिक-डेटा endpoint है जो FRED, BLS, World Bank और IMF को मैक्रो-जागरूक एजेंट्स के लिए एक ही प्राकृतिक-भाषा कॉल के पीछे जोड़ता है।
2026 में AI एजेंट्स के लिए सबसे अच्छे Web Search API (तुलना)
Bing Search 2025 में बंद हो गया और एक दर्जन एजेंट-नेटिव सर्च API इसकी जगह लेने के लिए दौड़ पड़े। यहाँ एक व्यावहारिक, अद्यतन नक्शा है कि कौन क्या लौटाता है, कौन कैसे शुल्क लेता है, और अपने एजेंट में किसे जोड़ें।
Exa बनाम Tavily: आपके AI एजेंट के लिए कौन-सी सर्च API? (2026)
जब आप किसी एजेंट में सर्च जोड़ते हैं तो सबसे पहले दो नाम सामने आते हैं: Exa और Tavily। दोनों एक ही काम को विपरीत तरीकों से हल करती हैं। यहाँ है ईमानदार आमने-सामने की तुलना, असली API आकार और 2026 की कीमतों के साथ।
एजेंटिक सर्च बनाम SERP स्क्रैपिंग: एजेंट्स को एक अलग API की ज़रूरत क्यों है
बीस साल तक, एक सर्च API का मतलब था 'Google के परिणाम पेज को स्क्रैप करो'। AI एजेंट्स ने इस मान्यता को तोड़ दिया। यहाँ बताया गया है कि एजेंटिक सर्च असल में क्या है, यह क्यों उभरी, और पुराना SERP मॉडल कब अब भी समझदारी भरा है।
USPTO ODP API: /patent/applications/search, ऑथ और Python
Google Patents Public Datasets बिना किसी documented replacement के बंद हो गई, और USPTO ने 2026 के मध्य में PEDS को एक नए Open Data Portal में migrate कर दिया, रास्ते में pipelines तोड़ते हुए। 2026 में prior-art, FTO और IP-research workloads के लिए जो वास्तव में काम करता है, वह यहाँ है — छह विकल्प, साथ-साथ।
रेट-लिमिट में फँसे बिना वैज्ञानिक साहित्य-समीक्षा एजेंट कैसे बनाएँ
आज ही कच्चे arXiv + PubMed + Semantic Scholar पर एक साहित्य-समीक्षा एजेंट बना लीजिए और दस paper पूरे करने से पहले ही आप 429 से टकरा जाएँगे। यहाँ बताया गया है कि रेट लिमिट क्यों और बिगड़ी, PaperQA / Undermind भीतर-ही-भीतर असल में क्या करते हैं, और एक ऐसा कारगर पैटर्न जो असली समीक्षा-सत्र को झेल जाता है।
Polymarket बनाम Kalshi API: डेवलपर गाइड
Polymarket और Kalshi एक ही प्रिमिटिव चलाते हैं — CLOB पर हाँ/नहीं वाले कॉन्ट्रैक्ट — पर पूरी तरह अलग API के ज़रिए। एक EIP-712 साइनेचर और एक Polygon wallet की माँग करता है; दूसरा एक REST endpoint है जिसमें FIX वैकल्पिक है। अगर आप एक फ़ोरकास्टिंग एजेंट, एक आर्बिट्राज बॉट, या एक स्मार्ट-मनी मॉनिटर बना रहे हैं, तो यहाँ वह साथ-साथ गाइड है जो पहले से मौजूद होनी चाहिए थी।
Ayinde v Haringey के बाद citation पर आधारित UK केस-लॉ retrieval
Ayinde v Haringey ने रातोंरात UK की legal AI का गणित बदल दिया। एक barrister ने एक LLM से बनाए गए पाँच नकली केस उद्धृत किए और उसे Bar Standards Board के पास भेज दिया गया। hallucinated citations के अब पेशेवर-आचरण संबंधी परिणाम होते हैं। यहाँ citation पर आधारित UK केस-लॉ retrieval बनाने की डेवलपर गाइड है — TNA Find Case Law, legislation.gov.uk, neutral-citation parsing, और इसे एक कार्यशील agent में कैसे जोड़ा जाए।
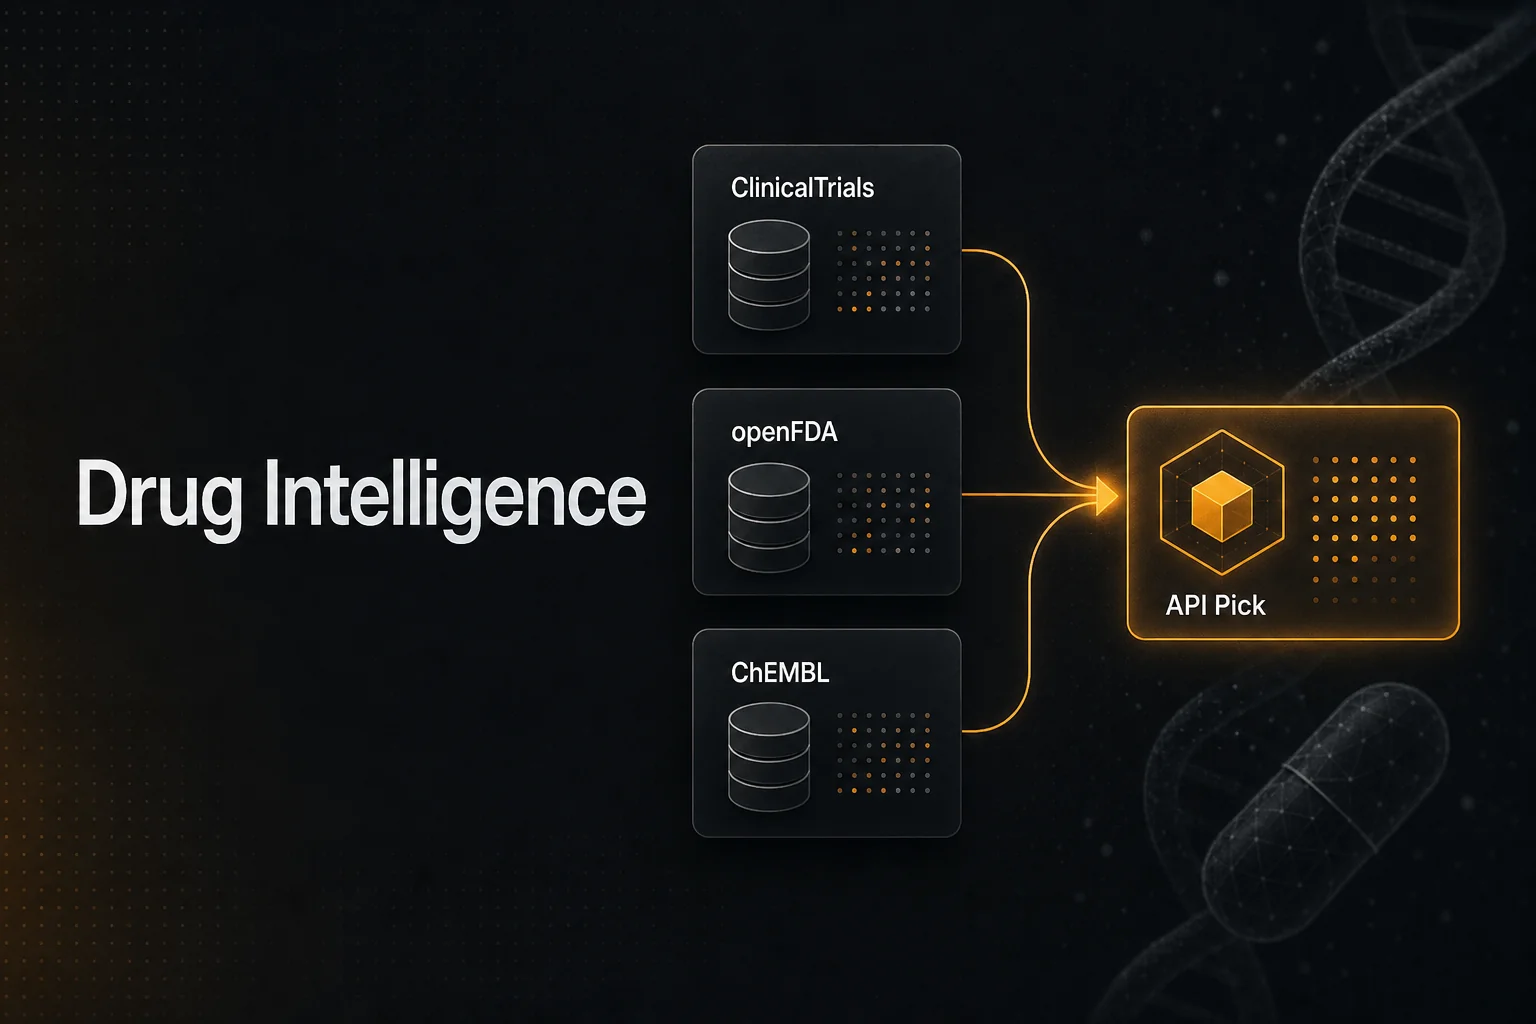
ClinicalTrials.gov v2 + openFDA + ChEMBL को एक लाइसेंस-क्लीन ड्रग इंटेलिजेंस endpoint में जोड़ना
फार्मा R&D, मेडिकल-AI स्टार्टअप, और फार्माकोविजिलेंस टीमें सभी एक ही चीज़ चाहती हैं: एक endpoint जो trials, लेबल, प्रतिकूल घटनाओं और बायोएक्टिविटी को लाइसेंस-क्लीन तरीके से खींच ले। यहाँ काम करने वाला architecture है, उन जालों सहित जिन्होंने production में टीमों को चौंका दिया है।
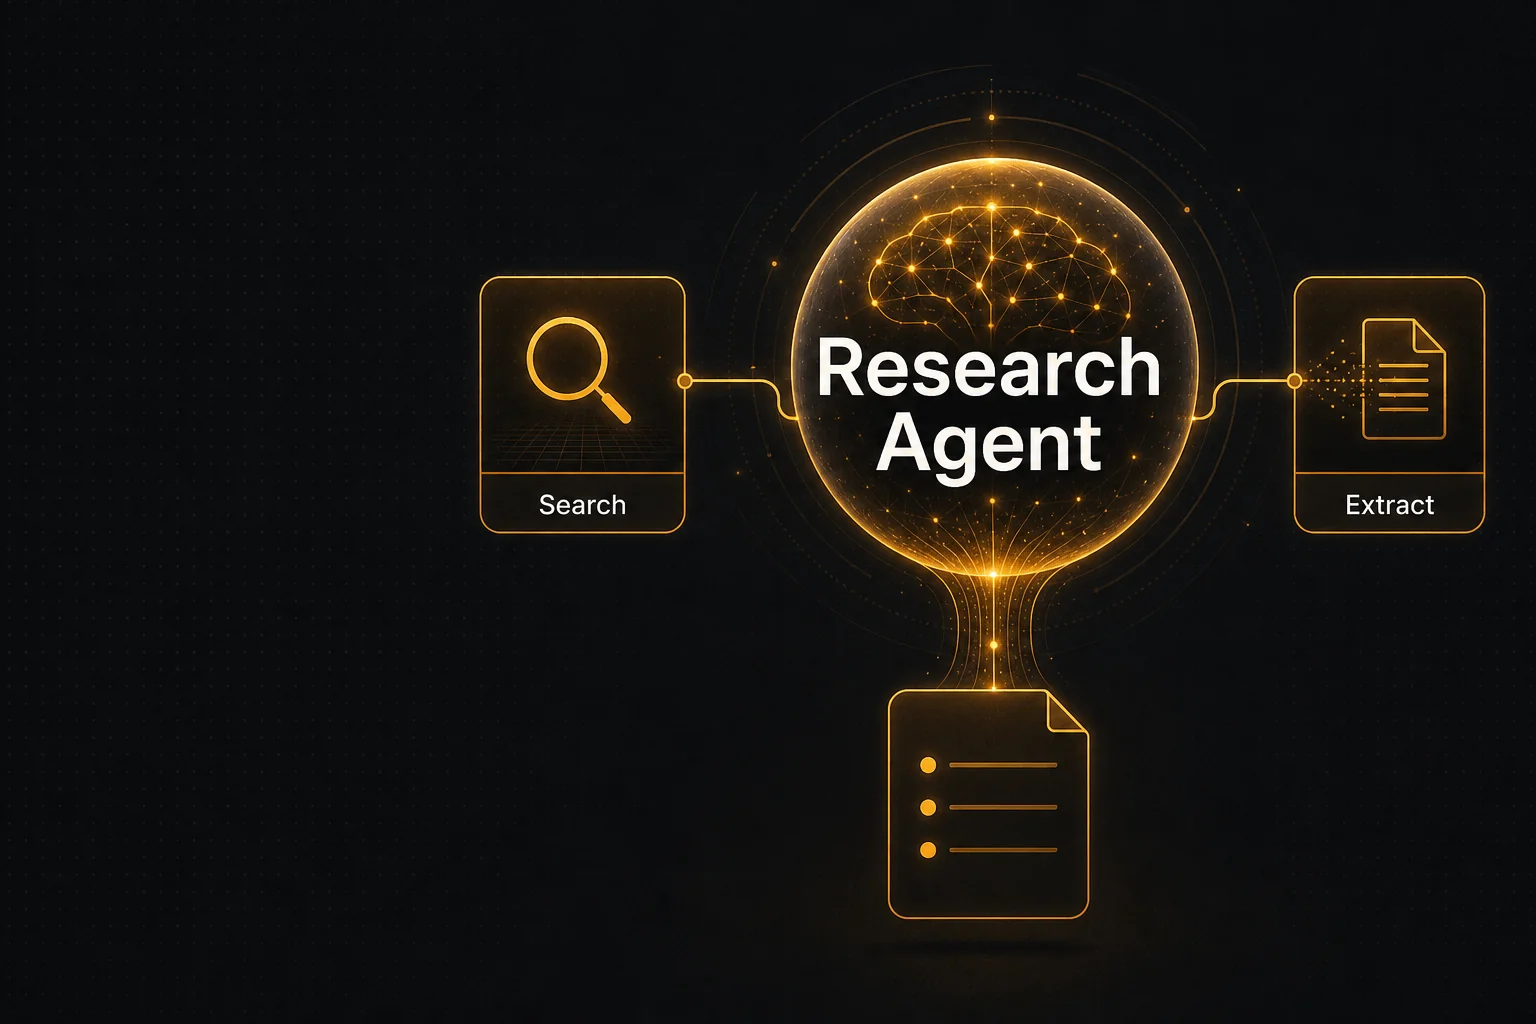
Search + URL Extract के साथ एक Research Agent बनाएं (Claude tool use, शुरू से अंत तक)
ज़्यादातर 'AI research agent' tutorials 'यह रही एक tool definition' पर ही रुक जाते हैं। यह एक काम करने वाला agent देता है: सवाल अंदर, citations के साथ जवाब बाहर। Search, extract, reason, cite — सब कुछ 120 lines के Python में।
SEC फाइलिंग्स (10-K, 10-Q, 8-K, अर्निंग्स) पर ड्यू-डिलिजेंस एजेंट बनाना
10-K पढ़ना ज़्यादातर Ctrl+F है। पचास कंपनियों के लिए यही करना एक पूरी नौकरी है। उबाऊ 80% को SEC EDGAR पर एक search-and-extract एजेंट से बदल दें — और जो 20% मानव ऐनालिस्ट के लिए मायने रखता है, उसे बचाए रखें।
APIs को केवल सफलता पर ही शुल्क क्यों लेना चाहिए — HTTP 200 बिलिंग का तर्क
ज़्यादातर APIs हर बिल योग्य कॉल पर शुल्क लेती हैं। AI एजेंट अस्थिर upstream सेवाओं पर लगातार retry करते हैं — जिसका मतलब है कि पुराना 'हमेशा शुल्क लो' मॉडल असल में resilience पर टैक्स लगा देता है। यहाँ केवल HTTP 200 पर बिलिंग का तर्क दिया गया है, और यह आपके एजेंट डिज़ाइन करने के तरीके में क्या बदलता है।
Tavily बनाम Exa बनाम Serper बनाम API Pick: LLM के लिए कौन-सा Web Search API चुनें?
Tavily, Exa, Serper और API Pick सभी आपके LLM की search परत बनने का वादा करते हैं। output स्वरूप, filters और billing में ये काफ़ी अलग हैं। agents प्रोडक्शन में भेजने वाले किसी व्यक्ति की ओर से एक तुलना।
Firecrawl vs Jina Reader: LLM के लिए URL एक्सट्रैक्टर
अगर आपने कभी ऐसा एजेंट शिप किया है जो URLs की एक सूची पढ़कर उन्हें संक्षेप में बताता है, तो आपने URL-सफ़ाई का टैक्स भरा ही है। Firecrawl, Jina Reader और API Pick Extract इसे अलग-अलग तरीके से हल करते हैं — यहाँ है व्यावहारिक तुलना।
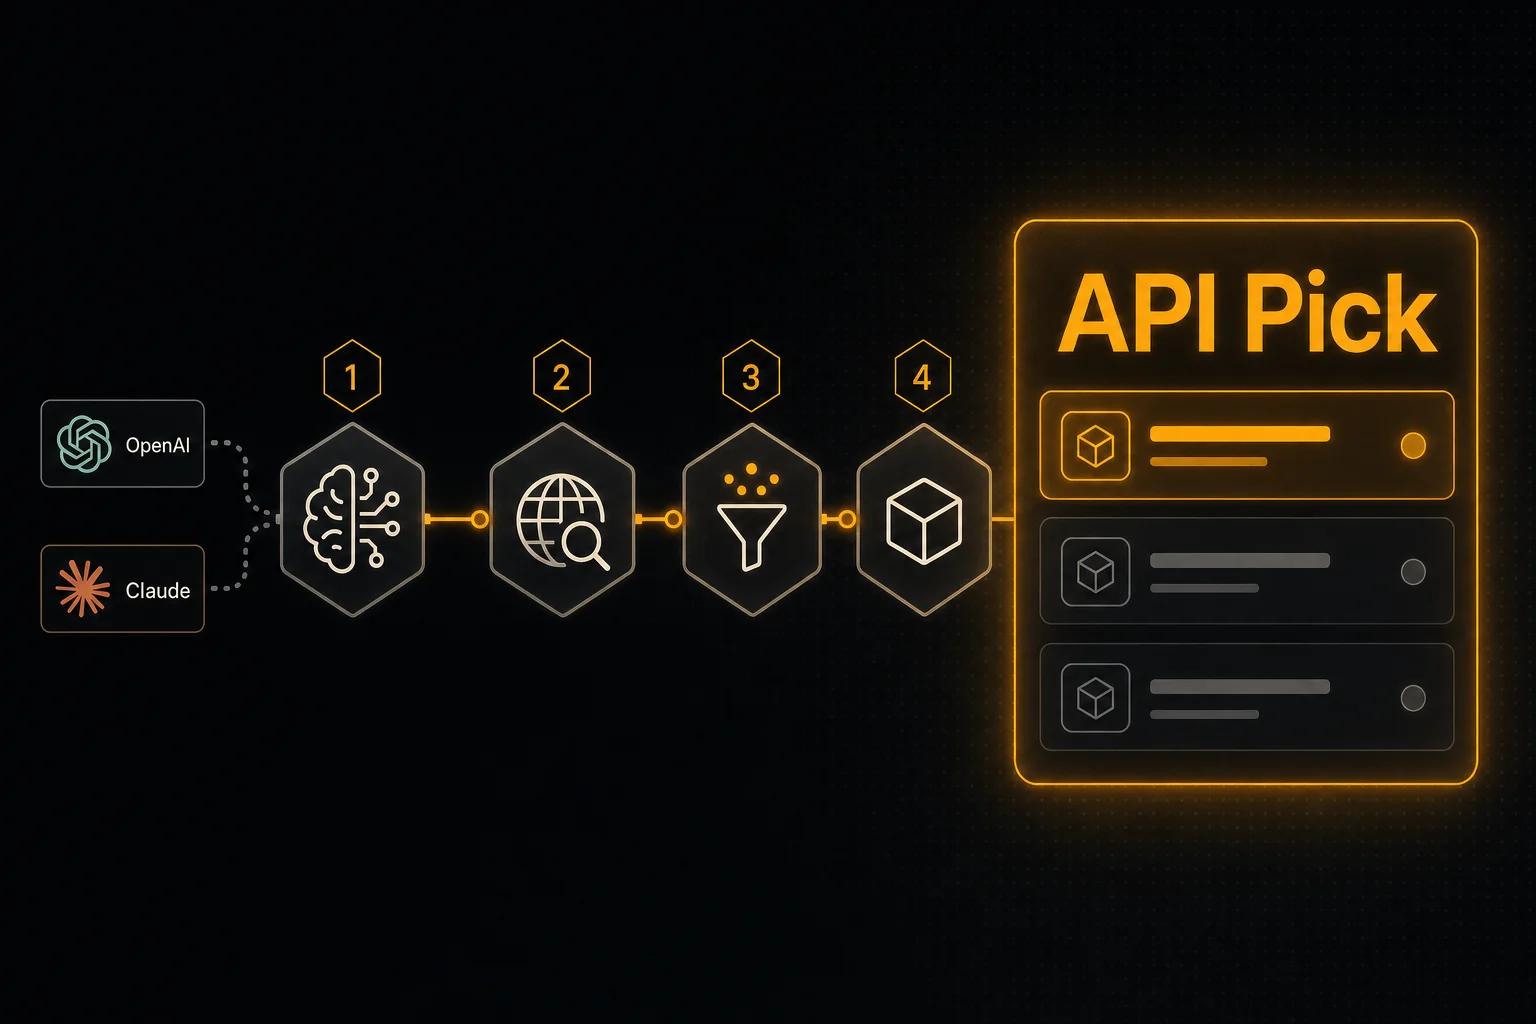
OpenAI या Claude एजेंट में रियल-टाइम Web Search को 4 चरणों में कैसे जोड़ें
चाहते हैं कि आपका एजेंट उत्तरों को मौजूदा जानकारी पर आधारित करे? आपको ठीक दो चीज़ों की ज़रूरत है: एक search API जो LLM-ready snippets लौटाए, और एक tool definition जिसे मॉडल call कर सके। यह गाइड दोनों को 4 चरणों में करती है।
News Search API के साथ एक मॉर्निंग ब्रीफिंग एजेंट बनाएँ
हर फाउंडर, PM और एनालिस्ट सुबह 8 बजे एक ही चीज़ चाहता है: रातभर में क्या बदला, इसका साफ़-सुथरा डाइजेस्ट। एक News Search API, एक LLM और एक HTTP-cron प्लेटफ़ॉर्म के साथ, आप इसे एक ही दोपहर में तैयार कर सकते हैं।